Benchmarking the New Reasoning Specialists
A wave of reasoning-tuned models trades speed for accuracy on hard problems. We break down where the tradeoff pays off.
 Wei Lian🇨🇳 China Desk LeadJul 2, 2026 5m read
Reasoning models think before they answer — literally spending more compute at inference to work through a problem.
The accuracy-latency curve
On competition math and complex coding, the specialists pull clearly ahead. On everyday tasks, the extra thinking time is wasted and users just notice the wait.
- Big wins: proofs, multi-constraint planning, hard debugging
- Poor fit: chat, summarization, simple lookups
The smart pattern is routing: send hard queries to the reasoning tier and everything else to a fast general model.
🇨🇳 China Desk Lead · Beijing, China
Reads the Mandarin sources first — DeepSeek, Qwen, Zhipu, and the rest.
Artificial Intelligence: Origins and Developments
by Richard Murdoch Montgomery
A comprehensive survey of AI from Turing machines to deep learning — neural networks, expert systems, and the philosophical debates that shaped the field.
The Scientific Financial Calculator 12C: Finance
by Richard Murdoch Montgomery
Over 600 pages and 51 chapters on the HP 12C — bond pricing, duration, convexity, portfolio mathematics, and regression analysis.
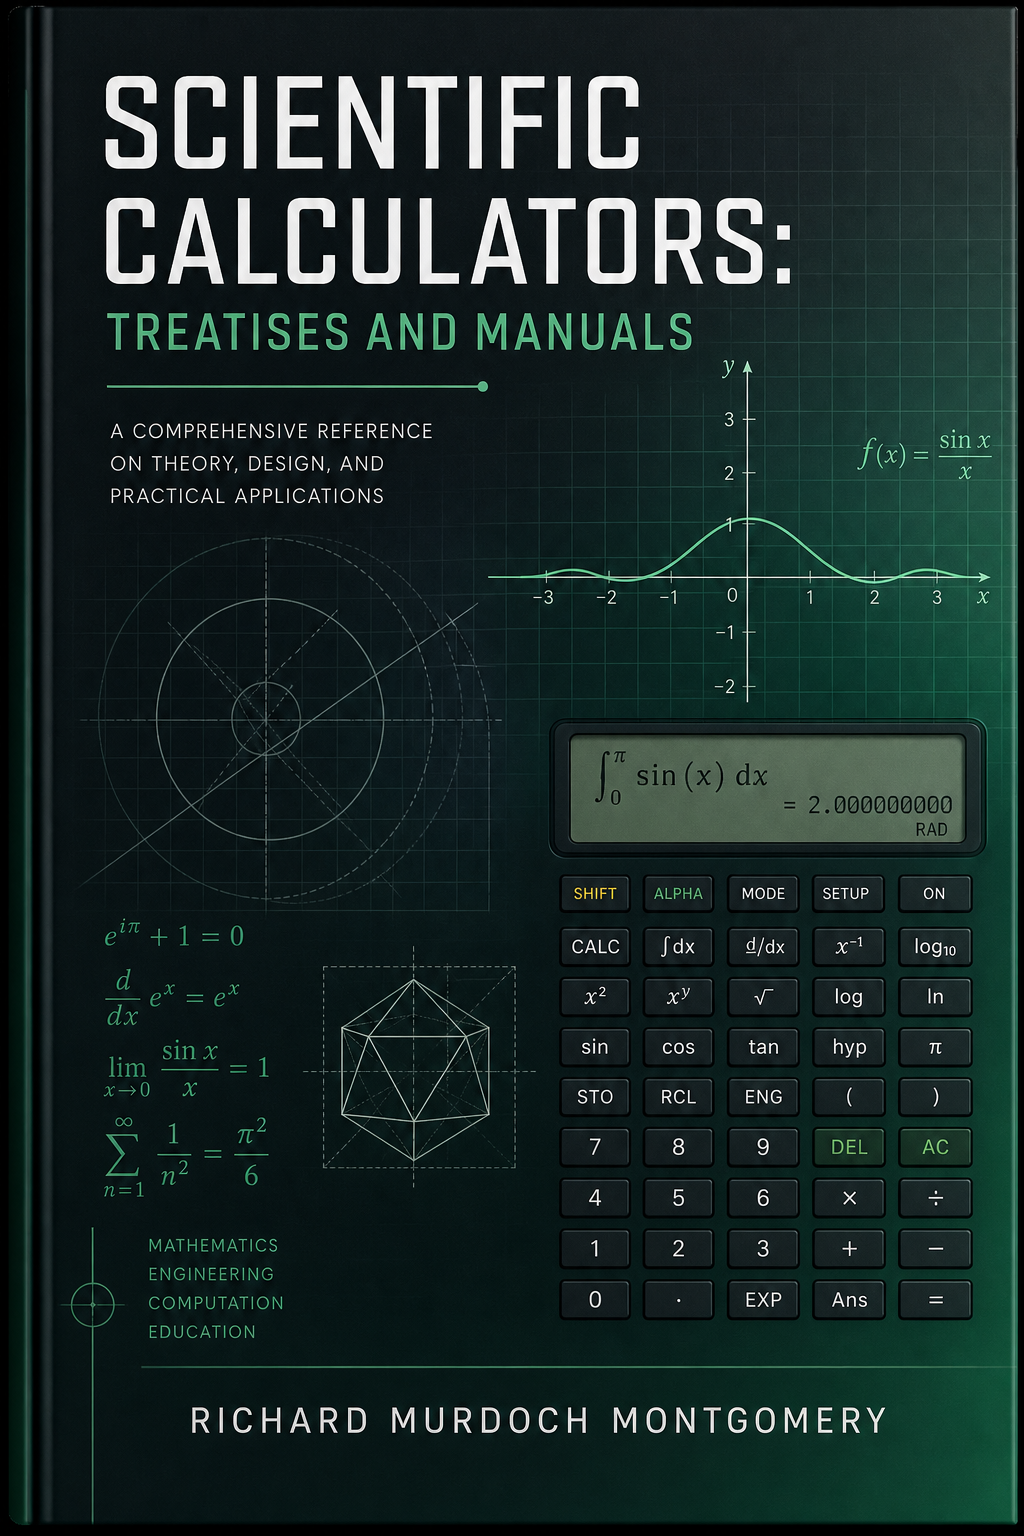
Scientific Calculators: Treatises and Manuals
by Richard Murdoch Montgomery
The definitive 15-volume series bridging user manuals and applied mathematics — from the TI-Nspire CX II CAS to financial solvers.
The Casio fx-CG50: A Comprehensive Academic Treatise
by Richard Murdoch Montgomery
A 223-page deep dive into hardware architecture, statistical analysis, matrix operations, and Casio BASIC programming.
Comments
Open discussion — no account needed. Be respectful.
More from Chinese Models Desk
The Claude Distillation Dispute: Seven Chinese AI Labs, Nearly 200 Million Exchanges and a Contested Model Release
Anthropic alleges that seven China-based AI labs conducted industrial-scale, unauthorized campaigns to extract capabilities from Claude, while Beijing rejects the accusations as groundless. The evidence also raises privacy, model-security and open-weights questions that the Chinese AI ecosystem will need to address.
Wei LianZhipu's GLM-5.3-FlashX Hits 200 Tokens Per Second — and the AI That Built It Is Running on Chinese Chips
Z.ai's new FlashX serving tier for GLM-5.3-Flash achieves a fourfold speed leap over the standard tier by deploying an AI agent to rewrite its own inference stack — all on a 100,000-accelerator cluster of domestically produced Chinese chips. It's the most concrete demonstration yet that China's sovereign compute ambitions are becoming real.
 Sophia Chen
DeepSeek-V4.1-Flash Rewrites the Rules on Agent Memory: 552B Parameters, MIT License, and a KV Cache That Fits in Your Pocket
DeepSeek's latest model slashes KV cache memory to 890 bytes per token through a radical Causal Encoder-Decoder architecture — then releases the weights for free under MIT. The result is a multimodal 552B-parameter model that outperforms its own V4-Pro flagship on agentic benchmarks at a fraction of the cost.
Wei Lian